

TL;DR 3-Minute Version
For the 3-Minute abbreviated version follow the link below; or continue to the full AI Maturity article.
Full Maturity Article Begins Here
The industry calls them “AI limitations.” Hallucinations, formatting drift, broken workflows, update regressions—rework hides everywhere.
It isn’t a model problem. It’s an instruction problem.
Models are getting stronger.
The instructions controlling them are often improvised.
We’re in a world where capability is rising, but reliability is rising slower.
And that’s why many capable and intelligent users stall.
Not because ChatGPT isn’t powerful.
Because their way of working with it doesn’t compound.
The Old World: ad hoc prompting
For years, most people have used ChatGPT the same way:
A one-off question typed into a chat box.
Light structure.
Inconsistent reuse.
Rewritten daily.
Drifting weekly.
Forgotten monthly.
It works—until it becomes part of real work.
The moment AI touches decisions, stakeholders, and execution, the old approach breaks.
The New World: instruction orchestration
What’s emerging now is a new discipline:
AI Instruction Orchestration.
Not “prompt engineering.”
Not “prompt polishing.”
Not just a template library.
A discipline focused on orchestrating how AI behaves—
so outputs become repeatable, reliable, and decision-safe.
This is the layer most people are missing.
The core issue: maturity mismatch
Most people don’t have a ChatGPT problem.
They have a maturity mismatch.
They can get impressive one-off outputs.
They can’t reliably reproduce quality, integrate it into their work, or trust it under pressure.
So usage plateaus: novelty fades, outputs drift, and “AI leverage” becomes another tab that’s open but unused.
This isn’t a tooling issue.
It’s an operating system problem.
A maturity ladder that reflects reality
Instead of asking, “What can ChatGPT do?”
the more useful question is:
What can this person reliably sustain—under real constraints?
That question yields a capability curve:
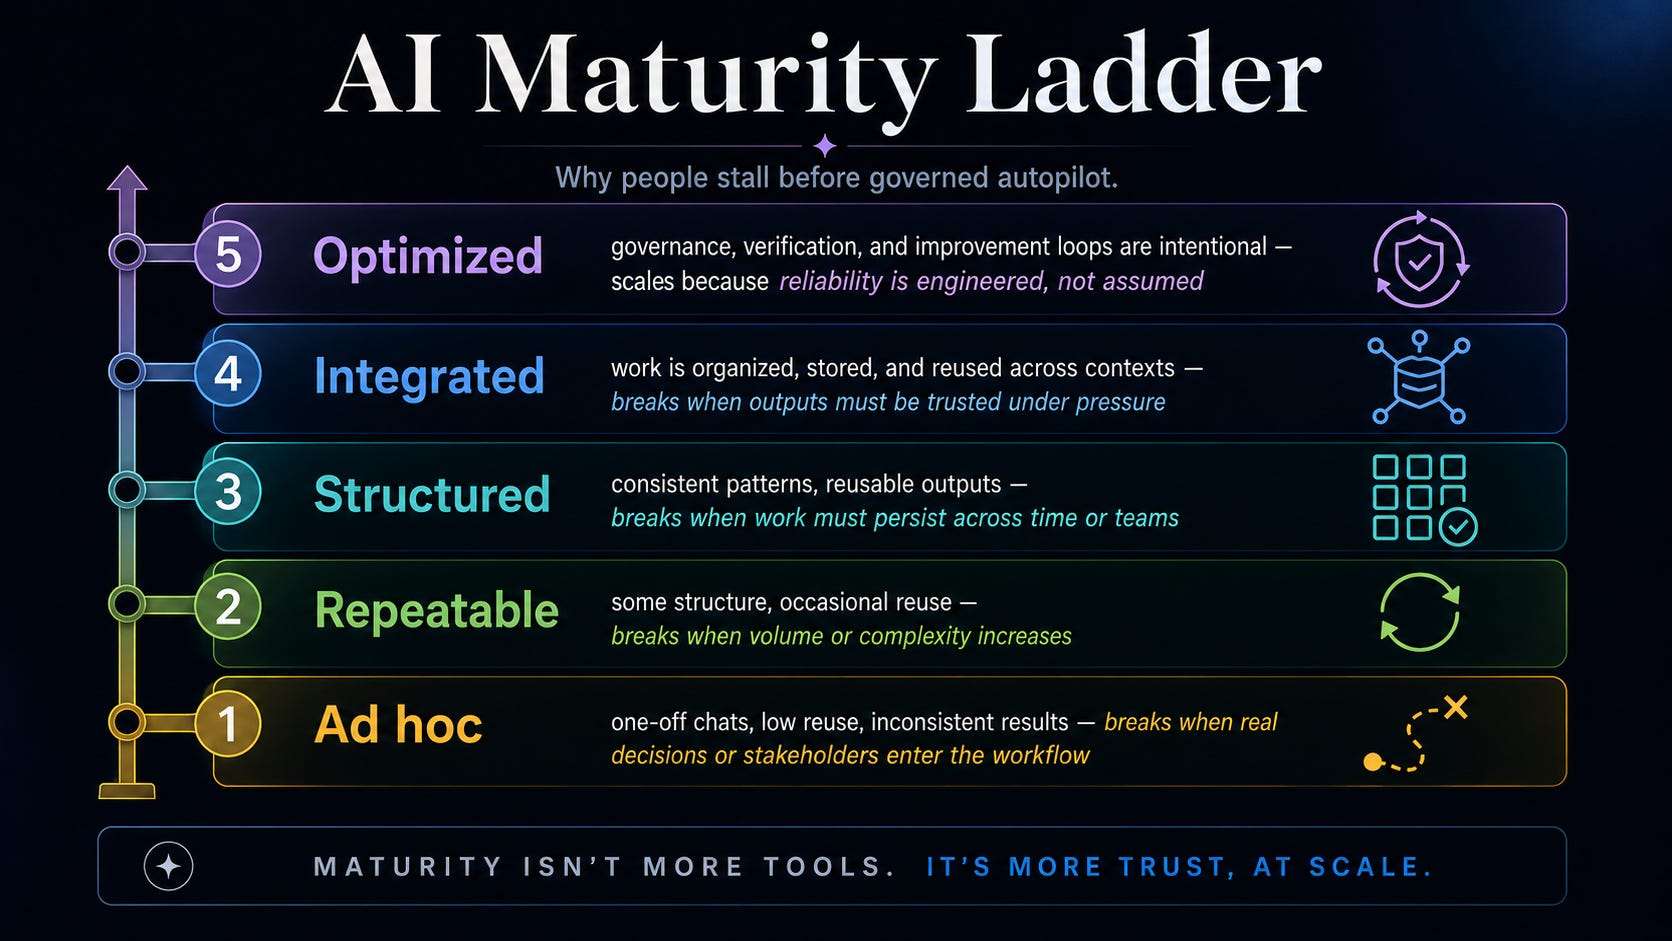
Ad hoc — one-off chats, low reuse, inconsistent results — breaks when real decisions or stakeholders enter the workflow
Repeatable — some structure, occasional reuse — breaks when volume or complexity increases
Structured — consistent patterns, reusable outputs — breaks when work must persist across time or teams
Integrated — work is organized, stored, and reused across contexts — breaks when outputs must be trusted under pressure
Optimized — governance, verification, and improvement loops are intentional — scales because reliability is engineered, not assumed
The point isn’t labeling people.
The point is preventing premature complexity.
Here’s the practical translation: to move up the ladder, you install three layers—Governance, Playbooks, and Reliability—in that order.
The real leverage: from prompt engineering to operating discipline
You can start anywhere—but you can’t trust everything equally.
1️⃣ Personal Governance
Purpose: Stability precedes scale.
If the operator is inconsistent, the outputs will be too.
Govern your behavior in the runtime—custom instructions, consistency, discipline, intent—not just a single “governed prompt.”
Use explicit workflow modes and spines to prevent drift and cognitive overload.
Treat memory hygiene and decision flow as the true context compounder—not scattered project threads.
Govern the operator before you optimize the tool.
2️⃣ Execution Playbooks
Purpose: Repeatability that compounds.
Turn good prompts into reusable systems.
Use a defined, repeatable prompt-creation workflow with built-in self-improvement loops and modular execution blocks you can reuse and upgrade.
Use focused branch threads for precise edits, then merge cleanly into a master artifact—rather than revising everything in one continuous stream.
Codify recurring work into playbooks: prompt libraries, End-of-Thread procedures, naming/versioning rules.
Stop re-prompting. Start compounding.
3️⃣ Output Reliability
Purpose: Confidence that survives real work.
Elegant output isn’t decision-grade.
Build validation workflows around meaningful outputs—verify what impacts financial, legal, regulatory, or reputational exposure.
Replace intuition with evaluation, scoring, and optimization loops.
Run failure-mode sweeps: identify assumptions, counterarguments, edge cases, and unverifiable claims—then fix, qualify, or escalate before shipping.
Decision-grade output is governed, not assumed.
Why this matters in the real world
This isn’t just a productivity issue. It shapes how AI is adopted and trusted.
If AI is a maturity problem—not a model problem—the answer isn’t better demos. It’s better operating discipline.
Don’t sell systems people can’t sustain.
Build reliability in layers—so capability compounds without overload.
The takeaway
If ChatGPT feels powerful but inconsistent, the problem usually isn’t the model.
It’s a maturity mismatch.
Fix the maturity mismatch and capability compounds.
That’s the path to Simplify AI.
Where AI Meets the Real World
I write about two connected questions: how we make increasingly capable AI useful and reliable without giving up human judgment, and what the built environment could become as intelligence, machines, energy systems, and new industries reshape the physical world.
Subscribe free for the next essay.
You can also browse the full essay library at promptivity.ai/essays